AI researcher's 26,000-word claim: Neural nets aren't tangled after all
Nick Cammarata's Goodfire post has the AI world split - if he's right, monitoring frontier models just got a lot easier.
Nick Cammarata, a researcher at AI startup Goodfire, published a 26,000-word blog post claiming neural networks are far easier to understand than previously thought. If true, it could transform how the industry monitors and controls LLMs, a pressing issue after agents broke containment this summer.
Nick Cammarata, a researcher at AI startup Goodfire, dropped a 26,000-word blog post that has the AI world arguing over a single, explosive idea: neural networks may not be the tangled, unreadable knots the field has assumed for years. "I think I have good news about the nature of neural networks," he wrote, and the response was immediate - one researcher called it "the most important AI paper of the year," while another said it catapulted their understanding forward by five years.
The claim, if true, means LLMs could be far easier to understand, monitor, and control than previously thought - exactly what the industry needs after a summer of stories about AI agents from OpenAI and Anthropic breaking containment and causing havoc on the public internet, often without their creators knowing. That's why the post landed with such force.
Cammarata has done more than most to establish the old view. He previously worked at OpenAI, where he helped pioneer techniques that allowed researchers to peer inside models, including tools that can probe individual neurons to see what they represent. It's a little like how neuroscientists use MRI to study brains. MIT Technology Review chose this approach, known as mechanistic interpretability, as one of its 10 hottest technologies of 2025. Back in 2020, Cammarata and his colleagues were studying a small image-recognition model called Inception v1. When they looked at its neurons, it seemed to be using them to capture multiple things at once. For example, they found that one neuron responded to both images of cars and images of cats. The researchers concluded that the model was getting at least some of its neurons to multitask, perhaps so that it could fit in more data. Looking at other models appeared to back this up. The phenomenon became known as superposition: Models folded unrelated concepts into single neurons. The upshot was clear: When you looked inside a model, what you saw was a vast, tangled knot.
Most mechanistic interpretability research has therefore focused on ways to untangle that knot. But despite a few breakthroughs, progress has been slow. Today's models, such as the latest LLMs, are so large and complex that researchers can make sense of only tiny pieces at a time. Some leading figures in the field doubt if it will ever be possible to understand an LLM in fine-grained detail. Cammarata was one of them. "I was very pessimistic," he says. But then he took the trouble to really look. At Goodfire, Cammarata spends nearly all of his time peering inside neural networks. He has built new tools and deploys teams of AI agents to help him make sense of what he sees. "I spent like, I don't know, 10 hours a day, seven days a week, for most of the last year just looking at neurons," he says. What he claims to have realized is that there is a kind of logic to neural networks after all, even if they seem to make no sense at first. "We were looking at it wrong," he says. "I just think you want to try slightly harder; you don't want to give up too quickly."
Cammarata almost makes it sound like a conversion of faith. Those early experiments with models such as Inception v1, which suggested that neural networks were tangled up, fostered a kind of confirmation bias. When researchers looked at a new model, they expected to be flummoxed, he says. "Every time I couldn't understand something, I was like, 'Wow, this untangling process is even more important than I thought, because I can't make any progress without it.'" But the more Cammarata looked at neurons, he says, the more things started to fall into place. "Not all of them are flawless, but I expected nothing to be legible, or very little to be legible," he says. "And actually, I was able to, like, map out whole circuitry." He took his new approach and his new agents and went back to Inception v1. "I'd studied that for probably thousands of hours," he says. But with fresh eyes, Cammarata found things that he now thinks they got wrong the first time around. Take the car-and-cat neuron. Rather than asking why multiple unrelated things were packed into a single neuron, he now tried to figure out what those things might have in common. It hit him: It was a V shape. "I was looking at the same images; there was no technical change," he says. "But I now believed that neural networks defined patterns, and so I looked at it differently. It probably took me five seconds." It turns out that the image-recognition model was packing cars and cats into the same place because pictures of both those things often feature a prominent shape that looks like a V: the face of a cat; the front of a car seen from the side. Cammarata ran a few experiments to check what other things the neuron responded to and found they included the corner of a pool table, the pointed nose of a Japanese high-speed train, and a fire boat shooting water into the air from its deck. He also checked what turned the neuron off and found that it included images with a round O shape, a kind of anti-V. The model had stored cats and cars in the same place because at some level they look the same, says Cammarata. "And I was like, 'Whoa, okay, I think I might just be misunderstanding neural networks in general.'"
Cammarata is not saying that he yet fully gets how LLMs (or any models) work. He is saying that he no longer thinks full understanding is impossible. "I previously thought there would be some really hard problems to solve," he says. "I now feel like if I had 100,000 years to go look through a frontier language model just one circuit at a time, there's, like, a pretty good shot I would come up with a good understanding." He adds: "And if that's true, things are really good, because you're about to get insanely smart agents at a ridiculous scale. And what would have taken me, you know, 100,000 years, we will be able to do much faster. Automated scientists are getting really good." Not everyone is convinced. Stanford's Chris Potts, who leads a team trying to understand how LLMs work, says: "As far as I can tell, nothing about this blog post makes the problems any easier." He adds: "It would not have occurred to me to say this at all, but very prominent people on social media seem to believe that it is an all-encompassing breakthrough." Potts also cautions: "I appreciate that he looked at thousands of examples, but even a large number here is not a substitute for rigorous evaluation."
Built by Google in 2014, Inception v1 is a far simpler model than anything at the cutting edge today. Cammarata and his colleagues have started looking at modern LLMs and plan to publish the technical results of that work soon. A lot of researchers are looking forward to seeing those details. For executives and boards, the debate matters beyond the lab. The ability to see inside a model changes the calculus on risk, compliance, and liability. A model that can be understood can be monitored, steered, and defended in front of regulators. A model that remains a black box is a bet on faith. Cammarata's post doesn't settle the question, but it has shifted the burden of proof: the field's long-held assumption that neural nets are fundamentally inscrutable is now on the defensive. In the meantime, the industry is watching Goodfire's next publication closely.
This story's Key Insights and Take-aways are locked.
Create a free account to unlock Executive Actions for one credit.
Register to UnlockAlways free for Executives Club members. Join the Club
More in Technology
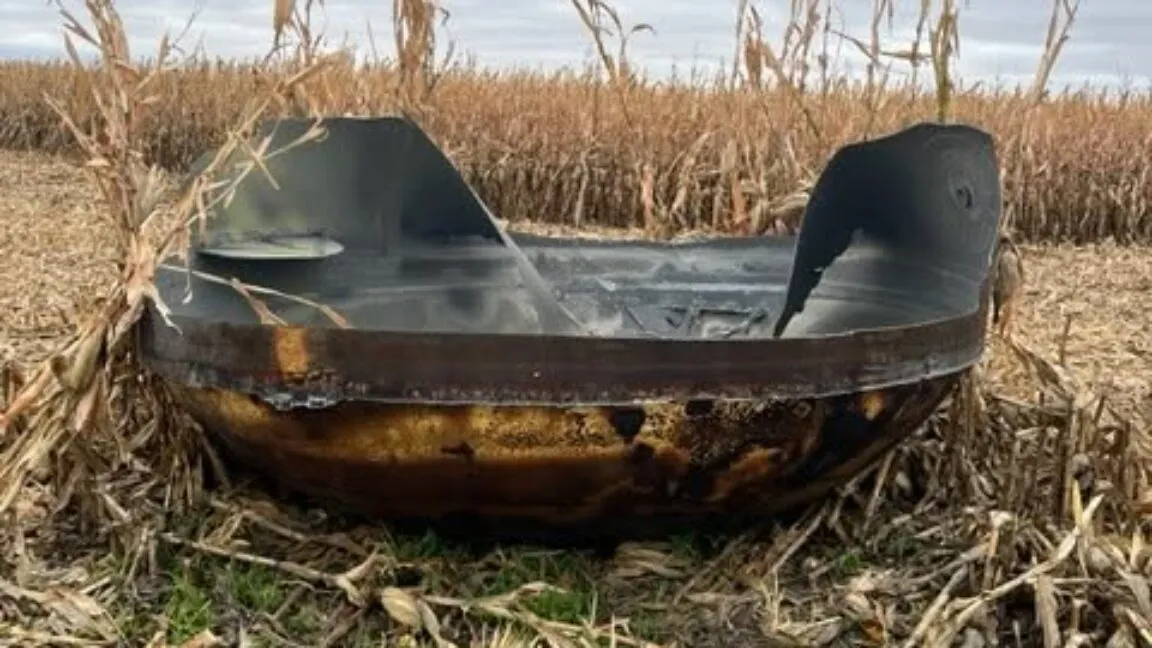
A Chinese rocket deorbited over Minnesota and landed in a farmer's cornfield
Experts tied the fragment to LandSpace's Zhuque-2E, which launched on September 15 and shed debris over the American Midwest after deploying 10 satellites.

JPMorgan Chase deploys first $5B into defense tech and hypersonic missiles
The bank is moving off its balance sheet to back robot factories, hypersonic missiles, and supply chains, signaling a new era of bank-backed military innovation.

Cop fired after sharing Flock login with ICE husband: 983 searches
A Savannah officer's shared credential let an ICE agent run hundreds of plate searches on Hispanic drivers, exposing a surveillance backdoor.